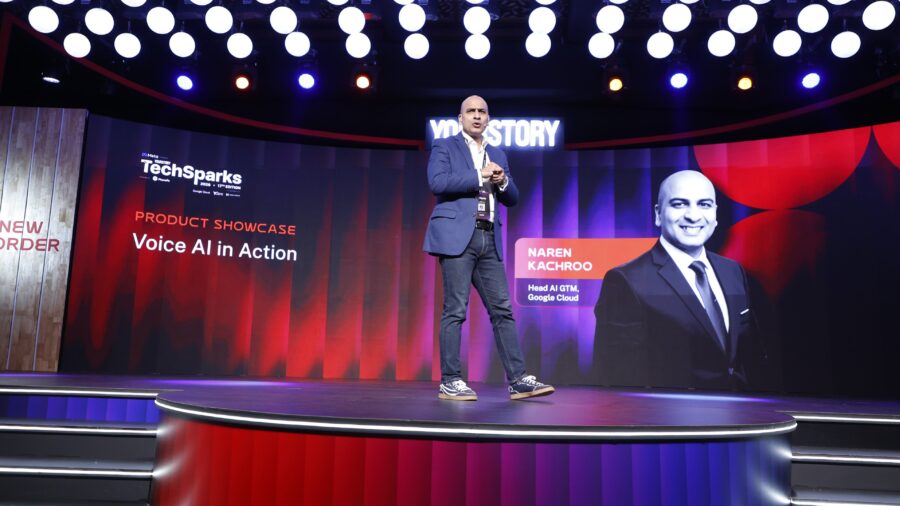
Google Cloud is shifting its generative AI strategy toward task-oriented voice models capable of executing complex actions, according to Naren Kachroo, Head of Sales and Go-to-Market for AI at Google Cloud. Speaking at TechSparks 2026, Kachroo emphasized that the industry has moved beyond simple question-and-answer chatbots toward systems that integrate with tools and data to complete specific assignments.
New Voice Models and Capabilities
Google recently introduced two distinct voice-to-voice models: Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking. The Gemini 3.8 Live model is designed for conversational tasks and can detect and switch between 97 languages within a single interaction. The Extended Thinking variant is intended for more complex processes that require multi-step reasoning, context switching, and deeper analytical capabilities.
Kachroo stated that while Extended Thinking provides superior reasoning, it also carries a higher cost per token. For developers with more specific needs, Google continues to offer separate models for text-to-speech, speech-to-text, and live translation. Internal testing indicates that these updated models perform effectively with diverse accents and regional tonalities, including those found in Indian languages.
Practical Applications in Business
Demonstrations at the event illustrated how these models function in real-world scenarios. One demo featured Shopify’s assistant, Sidekick, guiding a merchant through administrative tasks. Another showcased a voice agent managing a restaurant reservation, successfully handling complex queries regarding menu options and dietary restrictions while maintaining context throughout the conversation.
Google has also launched Live Avatar for enterprise customers, which combines live voice generation with real-time video and lip-syncing. This feature allows businesses to deploy animated, interactive interfaces for customer engagement.